Product Changelog

Stay up-to-date with all the improvements, features, and changes introduced to the product, APIs, docs, and other resources.

rss_feedSubscribe to RSS Feed

To protect your sites and their visitors, Launch no longer deploys Next.js versions that have a known critical security vulnerability, such as React2Shell (CVE-2025-55182).

  • After it installs your dependencies, Launch checks the installed version of next. If that version is on the list of blocked versions, the deployment fails and the deployment logs name the version.

  • Your current live deployment is not affected and keeps serving traffic until you deploy again.

  • To deploy again, upgrade next to the latest patch release of your release line, update your lockfile, and redeploy.

See the blocked versions and the version to upgrade to in Next.js on Launch.

New Features

  • Brand Profiles: Brand kits now support Brand Profiles, Markdown documents that give AI context about your brand, such as its voice, image style, and translation rules. You structure each profile the way your brand needs, with your own headings and sections.
  • Create profiles with Polaris: Describe the profile you need, optionally start from a template such as Voice Profile, and attach your existing brand guidelines (PDF, .txt, or .md files of up to 1 MB each). Polaris drafts the profile for you to review.
  • Write profiles yourself: Create a blank profile and write it in the Markdown editor, with an Outline of its headings and a formatted or Markdown view.
  • Use a profile in Polaris: In the Polaris composer, click +, select Brand Kit, and choose a profile. Polaris follows it when it writes or rewrites content, such as an entry in your stack.

Good to know

  • Brand Profiles aren't available in the AWS North America (NA) region yet. They will be available there later.
  • Brand kits that use Brand Profiles show a v2 badge. Existing brand kits keep their Voice Profiles, and you can continue to use them.
  • Drafting a profile with Polaris uses your organization's AI credits.

To learn more, refer to the Brand Profiles documentation.

Here’s an overview of the latest updates in Contentstack Launch:

  • Node.js 20 Deprecation:

    Node.js 20 is deprecated on Launch, and deployments that use it fail from December 2, 2026 (00:00 UTC). This includes deployments you start in Launch, automatic redeployments when content is published, and deployments triggered by deploy hooks. Your live site keeps serving its last successful deployment. To keep deploying, set the engines field in the package.json file at the root of your repository to 24.x, then redeploy each environment.

    Learn more in Supported Node.js Versions.

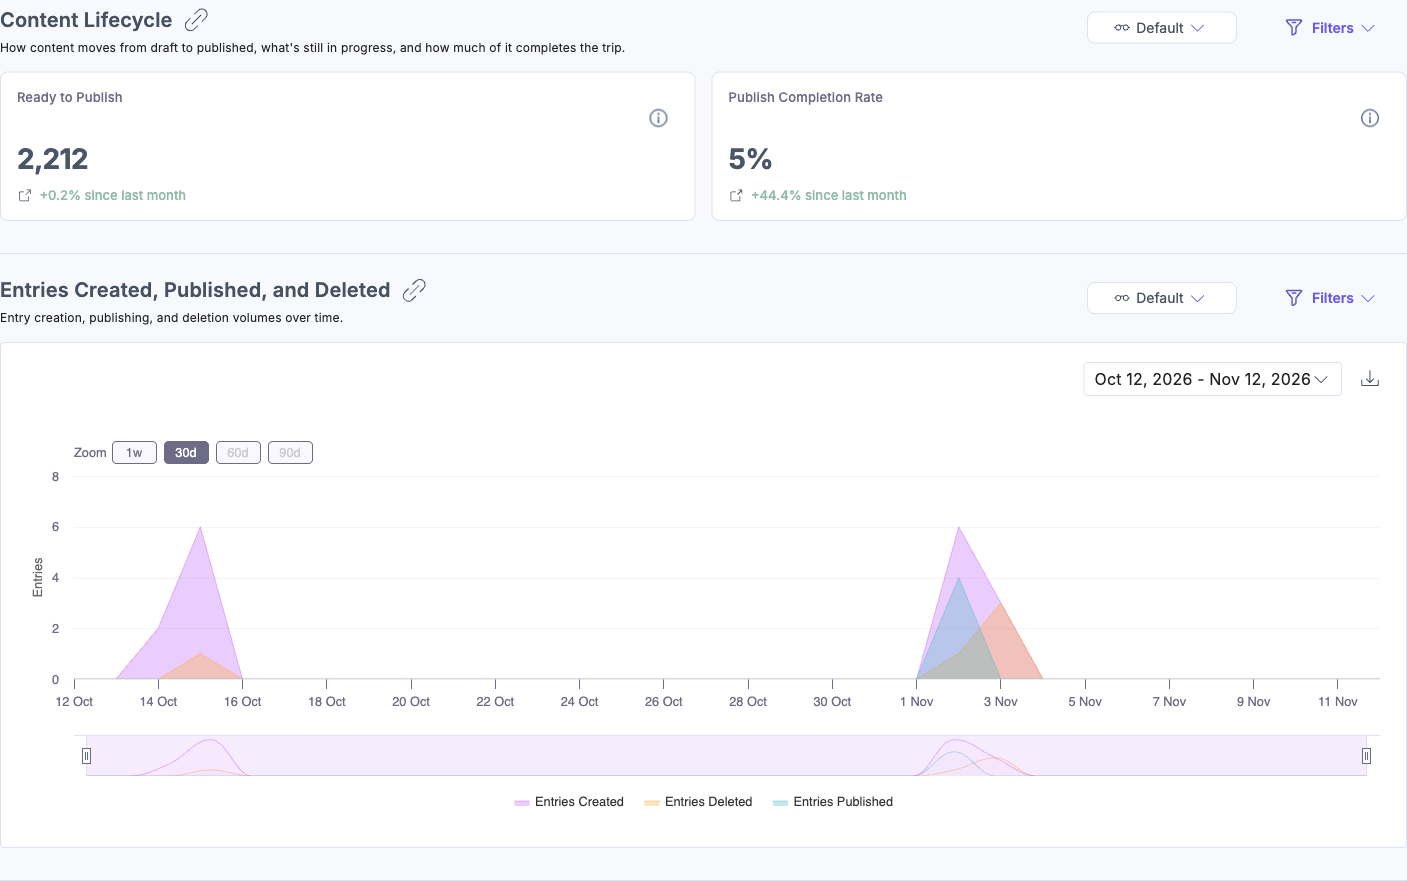
We've added five widgets to the CMS section of Analytics, so you can see how content moves from creation to publishing, right in the dashboard. You can now spot entries that have stalled in review, find content types publishing with no workflow attached, and see which authors are actually creating content over the last 90 days.

Content Lifecycle and entry trend widgets in the CMS section of Analytics

  • Content Lifecycle: See how many entries are complete and waiting to be published, and what share of the entries created this month have also been published.

  • Entries Created, Published, and Deleted: Track all three volumes on one trend chart, over 7, 30, 60, or 90 days, with CSV export.

  • Workflow Coverage: See how many entries sit in a workflow stage, how many have no workflow at all, and how many are covered by a publish rule.

  • Stalled Entries by Workflow Stage: Find the 10 workflow stages holding the most entries that haven't moved in 7 or more days, grouped by how long they've been waiting. A table lists each stalled entry with its stage, branch, locale, content type, stack, days in stage, and owner.

  • Team Activity: See active and inactive users over the last 90 days, the share of your organization that's active, entries created, and the average per author, with a per-user breakdown below.

Every widget supports saved views and section filters, so you can scope a section to a stack and keep that view for next time.

Check our documentation for full details, or contact support for more information.

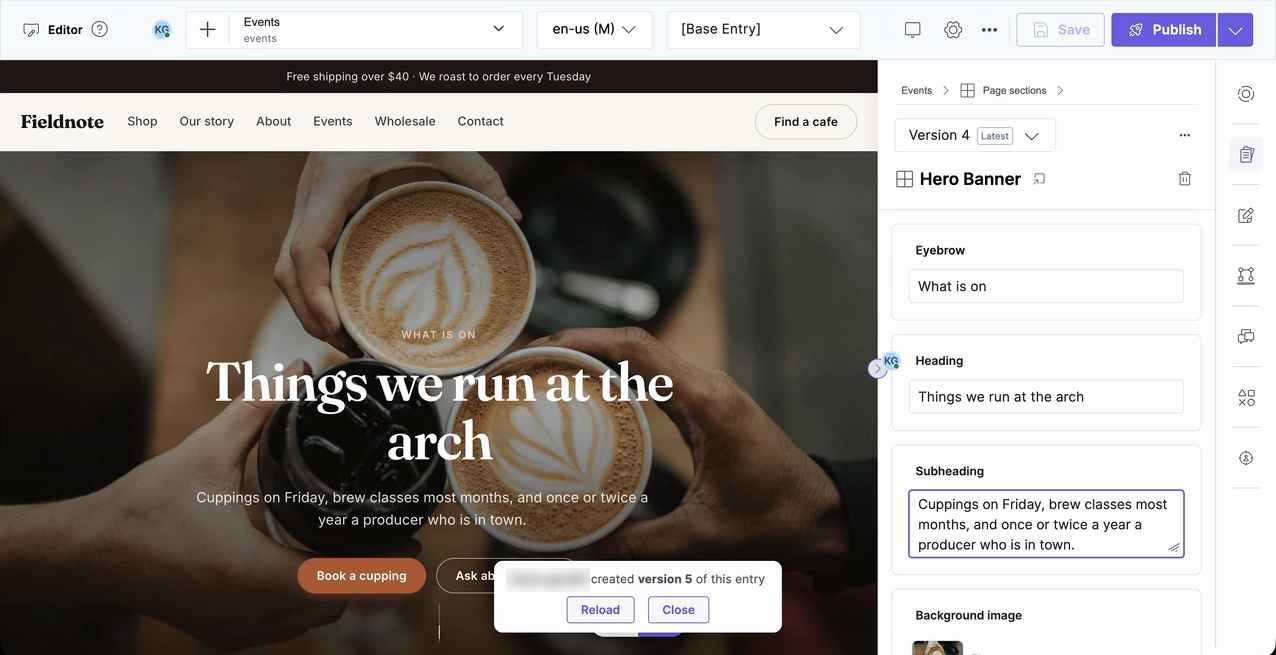
Visual Editor now shows when other users are working on the same content as you, the same way the entry editor does. You can see who else is on the page, and you are told when someone changes an entry the page shows.

With this update, you can:

  • See who is on the page: Avatars in the Visual Editor toolbar show the other users on the entries shown on the page.
  • See who is on a field: In the Form panel, an avatar next to a field shows who is on that field.
  • Get notified of changes: When another user saves or deletes the page entry or any entry shown on the page, or removes its localization, a notice names the user and the change. Click Reload to load the latest content, or Close to dismiss the notice. A notice about a deleted entry has only Close.

This works both ways. Users in the entry editor see Visual Editor users on the same entries and fields.

The Visual Editor toolbar and the Heading field in the Form panel show the other user's avatar, and a notice on the canvas says the user created version 5 of this entry, with Reload and Close buttons

No website setup is needed. Entries that load on the page after it opens are also tracked, and with Live Preview Utils SDK 4.6.0 or later they are picked up the moment they appear. Presence shows in the toolbar and the Form panel only, not on the canvas.

Learn more in the Edit Page documentation.

New Features

  • Create a File for every agent: Every custom agent, including on-demand agents, and Polaris can create files. The tool is provided to every agent by default, so there's nothing to add or configure, and it doesn't appear on the agent's Tools card. Ask for a file in the agent's instructions or in the request that runs it, and the reply includes a secure download link.
  • 16 file formats: Excel, CSV, TSV, JSON and XML for data; PDF, Word, Markdown, plain text and HTML for documents; PowerPoint for presentations; PNG, JPEG, GIF and WebP for charts and images; and ZIP to bundle several files into one download. Ask for charts by name, for example a PDF report with a bar chart. If you don't name a format, the agent uses CSV for tables and Markdown for text.
  • Send files to an agent: Send up to 3 files, 5 MB each, in the same HTTP request that starts an agent, as multipart/form-data in a field named files. Supported files are images (PNG, JPEG, WebP, AVIF), documents (PDF, Word, PowerPoint), text (TXT, Markdown, HTML, CSS, JSON) and data (CSV, Excel). The agent reads documents, gets a description of each image, and can pass a file on to its tools, for example to upload an attached image to your stack as an asset.

Enhancements

  • File size: An agent can create files up to 5 MB by default, and the limit can be raised for your organization. If a file is too large, the agent tries again with a smaller file, for example with fewer rows, compressed, or split into parts.
  • Execution log: A Create A File step shows a file card with the file name, size and time until the link expires, plus buttons to copy the download link and download the file. For runs started with files, the run's Input lists each file under attachments with its name, size and type.
  • Existing agents keep working: Agents that already have the older Create a File tool attached keep using it for CSV, JSON, Markdown and plain text, with the same output and file name as before. Every other format comes from the built-in tool. To use only the built-in tool, remove the older one from the agent's tools.
  • Clear rejections: A request with an unsupported file type, more than 3 files, a file over 5 MB, or a file in a field other than files is rejected before the agent runs, with an error that names the file and the rule. No AI credits are used.

Automations continue to use the Create a File action of the Files by Agent OS connector for CSV, JSON, TXT and Markdown files.

To learn more, refer to the Files by Agent OS, Send Files to an Agent, and View Execution Log of Agent OS documentation.

New Features

  • Canvas editor: Build automations visually on a single zoomable canvas. See the trigger, actions, If-Else branches and loops together, and configure and test each step in a side panel without leaving the canvas.
  • Switch editors at any time: Open an automation and click Try Canvas Editor. Your choice is remembered, so your other automations open in the Canvas editor too. To go back, click Switch to Form Editor. Both editors use the same steps and labels, so an automation behaves the same way in either one.
  • Add steps from one panel: Click + below a step to open the Select Step panel, with All, Apps, Logic and Utilities tabs. Under Logic, add an If-Else step that splits into Matches and Else branches, or a Loop that repeats over a data source or a set number of times (up to 100 by default).

Enhancements

  • Find your way around: Search for a step by its name, app or step type and jump straight to it. Use Fit to view to see the whole workflow, or zoom in and out.
  • Manage steps in place: From each step's menu, Rename it, Add Note, Duplicate it, Copy and Paste below to move it, Replace Action, or Delete it.
  • Executions and settings with the automation: Each automation has Builder, Executions and Settings tabs. Executions show the input and output of every step, including loop iterations and If-Else branches. Settings cover throttling, cloning (clones open in the Canvas editor), export and import, share links and deleting the automation.

Good to know: Activating an automation makes its canvas read-only, and a Loop can't be added inside an If-Else branch.

To learn more, refer to the Build Automations with the Canvas Editor documentation.

Content managers have always picked modular blocks by name. Now they can see them. Content modelers can give each block a preview image and group blocks into categories, so content managers find and add the right block by what it looks like, in the entry editor and in Visual Editor.

This release introduces:

  • Preview images for blocks, chosen from your assets or uploaded in JPEG, PNG, or WEBP up to 5 MB, set from a block's Manage Preview and Category option in the content type and global field builders
  • Categories on a Modular Blocks field, created in the field's properties and assigned per block, so related blocks are grouped together
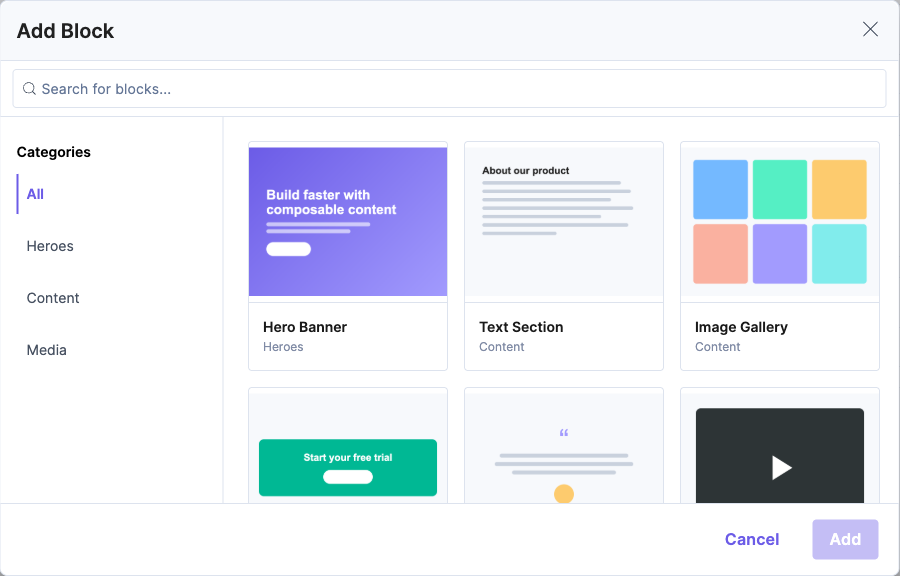
  • An Add Block dropdown in the entry editor that shows each block's image, with View All opening a modal to browse every block by category, search by name, and add several blocks at once
  • The same image and category view when adding a block in Visual Editor, from the Form panel or the canvas
  • Preview images and categories in the content type and global field schema, for teams that manage content models through the Content Management API

Previews and categories are available to all organizations. A Modular Blocks field keeps its existing block buttons until at least one of its blocks has a preview image or the field has a category.

The Add Block modal showing each block as a card with its preview image and category, with category filters on the left and a search box

Learn more about Modular Block Previews and Categories.

You can now edit Select, Taxonomy, Boolean, and Tags fields from a popup on the Visual Editor canvas, without opening the Form panel.

With this update, you can:

  • Select: Pick a value from a dropdown, radio buttons, or checkboxes, including fields that allow multiple values.
  • Taxonomy: Remove terms, or add terms from the term picker.
  • Boolean: Switch the value on or off.
  • Tags: Add or remove the entry’s tags.

To edit a field, click it on the page, click Edit in the field toolbar, change the value, and click Apply. The page updates right away.

Editing Select, Taxonomy, Boolean, and Tags fields from the Canvas Quick Edit, Is Archived?, and Tags popups on the Visual Editor canvas, with each change showing on the page after Apply

Your website must use Live Preview Utils SDK 4.6.0 or later. To edit tags from the canvas, the website must also render the entry’s tags with an edit tag.

Learn more in the Edit Page documentation. To set up your website, see Set Up Live Edit Tags for Entries with REST.

New Feature:

  • Added the opt-in Contentstack.Builder.setSerializeNulls(boolean) option. When you enable it, the SDK sends null values in request bodies to the API instead of dropping them, so you can clear a field's value (for example, a Number field on a localized entry). The option is off by default, so existing behavior does not change.

Security Fix:

  • Fixed security vulnerabilities in the SDK dependencies.

Enhancements

  • Page awareness: In the Visual Editor, Polaris knows the open page, its language, the audience you are viewing, and the entries behind each part of the page.
  • Saves to the right entry: Polaris saves changes to the entry and language behind the page and shows them in the preview without a reload.
  • Language versions: Polaris adds a missing language version of a page, including a page URL for that language.
  • Audience edits: Polaris applies changes only to the audience variant you are viewing.
  • Open another page: Polaris replies with a link to open another page or language instead of switching the page you are on.

To learn more, refer to the Get Started with Polaris and Polaris Features documentation.

New Feature

  • Custom Models (Bring Your Own Key): Power Polaris and Custom Agents with your own LLM provider and credentials. From AI Settings > Custom Models, configure OpenAI for Polaris, and OpenAI, Azure OpenAI, Google Vertex AI, Google Gemini, or Anthropic for Custom Agents. You can also set a custom model for an individual agent in its Settings.

To learn more, refer to the AI Settings: Custom Models (Bring Your Own Key) documentation.

Analytics already tells you how many API requests your organization made. Traffic Explorer tells you which ones. It is a new dashboard that shows the individual API requests behind your aggregated usage metrics, so you can find a single request, read its status code, response time, and country, and act on it without raising a support ticket.

Key Features

  • Request-level visibility: View logs for requests served across images, assets, CDN, and GraphQL.
  • Targeted filtering: Combine filters such as status code, URL, host, country, client IP, environment, and API key to isolate the requests you care about.
  • Faster debugging: Investigate error spikes and slow responses by looking at the exact requests behind them.
  • Reusable views: Save a filter set as a named view and reapply it in one click.
  • Export: Download up to 1,000 of the requests behind your current filters as a CSV file for offline analysis.

Traffic Explorer keeps the last 7 days of request logs, and a request becomes searchable within 15 to 20 minutes of being made. Request and response payloads are not captured.

Note: Traffic Explorer is available in Early Access, in the AWS North America and AWS Europe regions only, and is not enabled by default for every organization. If you do not see it in Analytics, reach out to support to have it enabled.

Check our documentation for full details, or contact support for more information.

New Feature

  • commercetools connector: Connect your automations to commercetools with 12 actions. Create, retrieve, and update products and customers, retrieve orders and update their states, create carts, and manage inventory. Product names and descriptions can be written in any of your project's languages.

To learn more, refer to the commercetools documentation.

New App

  • SAP Spartacus Connector: Make Contentstack the CMS engine for an SAP Composable Storefront (Spartacus), while SAP Commerce (OCC) stays the commerce engine. The connector runs in hybrid mode — SAP renders the base of every page and Contentstack overrides only the slots you author.

To learn more, refer to the Install the SAP Spartacus Connector documentation.

Adaptive Rate Limiting changes how your organization's rate limits for the Content Delivery, Image Delivery, and GraphQL Content Delivery APIs are enforced, so short, legitimate traffic spikes are served instead of rejected. Your rate limit stays the same. What changes is how it is measured: smoothly over time, with no fixed one-second windows.

What you can do with it:

  • Absorb bursts: Send a burst of requests at once, up to a configured percentage of your rate limit, with capacity that refills continuously.
  • Smooth requests instead of rejecting them: With request smoothing, a request that arrives after your burst capacity runs out is held for a few milliseconds and then served.
  • Retry with clear guidance: A 429 response includes a Retry-After header that tells your application how long to wait.

Note Adaptive Rate Limiting is currently part of an Early Access Program and is available on request. In this phase, it applies only to the Content Delivery, Image Delivery, and GraphQL Content Delivery APIs. To enable it for your organization, contact support.

Check our Adaptive Rate Limiting documentation for full details.

The entry and asset list and detail pages now show the publish status for every environment in your stack, including environments your role cannot publish to. You can check where content is live, such as in production, before you edit or delete it.

Key Benefits:

  • See whether an entry or asset is published to each environment, not only the ones you can publish to
  • Avoid changing or deleting content that is live in an environment you cannot publish to
  • Keep publish access unchanged, because seeing a publish status does not let you publish to that environment

No role configuration is needed, and existing roles are not affected. Learn more in our Publish an Entry and Publish an Asset documentation.

Enhancement

  • Get User Information action: The Contentstack Management Get User Information action can now also return the roles assigned to a user and the permissions those roles carry. Turn on Show Optional Fields, then select Include roles (and choose a stack) and, optionally, Include permissions.

To learn more, refer to the Contentstack Management - Users Actions documentation.

New Feature

  • Run an agent on demand: Build an agent once, then run it interactively from a Polaris conversation whenever you need something done, instead of waiting for an event or a schedule. Type @ to pick the agent, or use the Run button in the Agent Builder.
  • Runs as you: An on-demand agent acts as the person who runs it, using their connected accounts, their permissions, and the inputs they supply for that run, all recorded against their name.
  • Per-run inputs: Define the inputs the agent asks for on every run, and choose which tool fields the runner fills in.
  • Interactive: Watch each step stream live, answer the agent's questions mid-run, approve changes before they happen, and open a full execution log afterward.

To learn more, refer to the Run an Agent On Demand documentation.

New Feature

  • Polaris Skills: Create reusable, named sets of instructions that Polaris applies whenever they are relevant, such as your naming conventions, your tone, or the checks that must always run. Keep a skill private, share it with specific people, or make it available to your whole organization.
  • Two ways to create: Build a skill from the Skills page, or ask Polaris to draft one for you in a conversation.
  • Deliberate or automatic: Run a skill on demand by typing / in the composer, or let Polaris apply it automatically when your request matches the skill's description.
  • Sharing and governance: Control access with Restricted or organization-wide sharing, assign Can use or Can edit, and mark organization-wide skills as required so they reach everyone.

To learn more, refer to the Get Started with Polaris Skills documentation.

New Feature

  • Build an agent from a Polaris conversation: Describe what you want in plain language, and Polaris interviews you for the few things it needs, selects matching tools, writes the instructions, and creates a draft agent. Review and publish it from the Agent Builder — the fastest way from an idea to a working agent.

To learn more, refer to the Build an Agent in Polaris documentation.

New Feature

  • Polaris Full Screen Mode: Open Polaris in a full-screen workspace — your chats, Skills, and Agents in one place, with more room to work.

This release brings more control over asset metadata, a way to clear out duplicate images, AI metadata written for you at upload, and a listing that remembers how you left it.

  • Select type user-defined field: A Select field captures metadata from a list you define instead of free text, so values stay consistent and filter together. Show the choices as a dropdown, radio buttons, or checkboxes. Read more in Configure Select Fields.
  • Duplicate Management for Images: Identical images are found in the background and grouped into sets. Open Duplicate Management from the asset listing to review the copies and keep the one you want. Nothing is flagged during upload. Read more in Manage Duplicate Images.
  • AI metadata at upload: Configure a space to write AI tags and alt text into assets as they arrive. Anything the uploader supplies is never overwritten. Read more in Auto-Populate AI Metadata at Upload.
  • AI suggested metadata in the API: Read the tags, alt text, objects, colors, and safety flags Contentstack generates for an image, and enrich content from your own systems. Read more in the Assets API documentation.
  • Persistent user preferences: The asset listing remembers how you left it. Your page size, view mode, column layout, sort order, and filters are saved to your account rather than to the browser, so they follow you to any browser or device you sign in from.

We are looking forward to seeing what you build with these.

Note: Assets is a paid add-on and it may not be enabled for your organization. Duplicate Management is being rolled out gradually and may not be available to you yet. To purchase Assets or to ask about availability, contact our support team.

Contentstack is no longer just for the world’s best enterprises. Starting today, anyone can now create a Contentstack account and start using our leading headless CMS and other powerful apps to build their next great project. Simply visit the Sign Up link to get your organization set up, create your first stack, and run your subscription yourself from the Subscription page in your account settings, click your avatar, then Manage Subscription. This new offering is a perfect fit for smaller teams and individual builders who want to get started and grow at their own pace. What will you build with Contentstack?

Key Features:

  • Create your account and start building: Sign up, verify your email address with a verification code, set your password, and create your first stack. Compare subscription options on our pricing page before you choose.
  • Pick the subscription that fits: Start on Free and move up to Build or Growth as your needs change, with a clear view of what you are charged today before you confirm.
  • Extend with add-ons: Add capacity to your subscription and adjust quantities as your usage grows.
  • Track usage against your limits: The Usage Overview shows where your organization stands on every resource your subscription includes, so you know before you run out rather than after.
  • Turn on extra usage: Keep working past an allowance instead of hitting a hard stop, with the option to cap how far it goes.
  • Keep your billing details current: Update your card, billing address, and invoices in the billing portal whenever you need to.
  • Change course at any time: Cancel your subscription from the Subscription page on your own terms.

To see the limits that apply to your organization, check your own Subscription page, it is always current for you.

Check our documentation for full details, or contact support for more information.

You can now run a bulk action on every entry in the entries list instead of only the entries on the current page. If a search returns 200 entries, you no longer select 100, run the action, and repeat it for the rest, select all records and run it once on all 200.

From the entry list page, you can:

  • Select beyond the current page: Select the checkbox in the table header, then click Select all {number} entries in the banner that appears.
  • Run the bulk actions you already use: Publish, unpublish, delete, and add to release all work exactly as before, only the size of the selection changes.
  • Filter first, or do not: Apply search, filters, or a view to narrow what you select, or select everything the list shows.
  • Review before you act: Click Show Selected to see every entry in the selection, and Clear selection to start over.
Note
  • A single action covers up to 10,000 entries and runs as one background job that you can track in the Stack Bulk Task Queue.
  • Select all records applies to entries only, and it does not support bulk workflow updates or export.

Check our documentation for more details.

Behavioral change: The limit query parameter now accepts positive integers only.

Passing limit=0, an empty value, or a non-numeric value now returns the default number of records for that resource instead of all matching records. Previously, limit=0 returned every matching record, which could cause requests on large stacks to time out.

If your integration relies on limit=0 to fetch a full result set, update it to paginate:

  • Set an explicit limit and page through the results using the skip parameter.
  • Pass include_count=true to retrieve the total number of records available, and continue paginating until you have retrieved that total.

By default, the response limit is 100 records per request. To retrieve the complete result set, specify an appropriate limit and use the skip parameter to retrieve each subsequent batch. For more information, refer to the Limit section.

We have introduced support for multiple identity providers in a Contentstack organization. An organization can hold up to five SAML 2.0 identity providers, each set up as a separate connection with its own certificate, session policy, role mapping, and login URL.

This suits organizations whose people do not all live in the same identity system: a parent company and an acquired subsidiary running separate tenants, employees and contractors on different providers, or a staged migration between providers where both need to stay live during the cutover.

Key Features:

  • Up to five connections per organization: Each connection is configured, enabled, and disabled independently from the Single Sign-On page in Administration.
  • A login URL for every connection: Each connection carries its own SSO ID, which forms its login URL. Share each connection's login URL with the users who should sign in through it.
  • A primary connection: Any enabled connection can be marked as primary. The primary connection supplies the SSO login link that goes out in organization invitation emails.
  • Per-connection session and role settings: Session time-out and IdP role mapping apply per connection, so the roles a user receives come from the connection they signed in through.
  • Metadata import: An identity provider's sign-in URL and signing certificate can be imported from a metadata URL or an XML file, rather than entered by hand.
  • Service provider metadata export: Contentstack's SP metadata for any connection downloads as an XML file, ready to pass to an identity provider team.
  • Organization-wide strict SSO: Strict SSO applies across the organization. If any active connection has it enabled, no user can sign in without SSO.

Existing SSO setups are unaffected. A connection that is already in place keeps its SSO ID, login URL, and Assertion Consumer Service URL, so SAML applications configured against it continue to work without changes.

Note: Support for multiple identity providers might not be available by default. To enable it for your organization, contact our support team.

Check our Configure Multiple Identity Providers documentation for full details, or contact support for more information.

Embedded entries and assets in the JSON Rich Text Editor (RTE) now resolve to their current metadata, so your rendered content no longer serves values captured when the entry was last saved. You can also retrieve nested embedded items in a single request.

With this release, you can:

  • Get current metadata automatically: Utils SDKs resolve asset and entry data from _embedded_items, so current metadata appears without stale or unpublished values leaking through, including for link-type references.
  • Resolve nested items in one call: pass include_embedded_items[]=RECURSIVE to resolve entry-to-entry-to-asset chains without a separate request per level.
  • Control the depth: use embedded_items_depth to limit how many levels are resolved, up to a maximum of 5.
Note
  • Existing behavior is unchanged. Omitting the parameter or using include_embedded_items[]=BASE returns the same response as before, so no migration is required.
  • Depth is capped at 5. Values above 5 are clamped to 5.
  • Higher depths increase payload size, so use the smallest depth you need.
  • RECURSIVE applies to GET requests only.

Check our documentation for more details, or contact support for more information.

We’ve made the Assets API available, so everything you set up in Contentstack Assets can now be driven from your own systems. The interface is built for a person working on one asset at a time; the API applies the same structures across thousands of them, on a schedule, or as a step in your release pipeline.

What you can do with it

  • Provision spaces and workspaces: Create spaces per brand, team, or region, add isolated workspaces for a campaign, and set their locales, so onboarding a new team becomes a script rather than a checklist.
  • Model assets around your business: Define asset types and custom metadata fields through the API, then write values onto assets in bulk. A taxonomy change can be rolled out across an entire library in one pass.
  • Localize without re-uploading: Manage localized asset variants and workspace locales programmatically, so opening a new market does not mean rebuilding a library by hand.
  • Automate governance: Read an asset’s full version history, fetch any specific version, and name versions so your audit trail matches your release process.
  • Enrich assets for interactive experiences: Set visual markups such as hotspots and bounding boxes, and apply image transformations, as part of your publishing pipeline instead of asset by asset.
  • Search the way the interface does: Combine nested filters, restrict a query to specific fields or spaces, page through results, work locale-aware with fallbacks, and use AI-assisted suggestions.
  • Work in bulk, and recover: Move, delete, and trash assets in bulk, and restore the ones you need from the bin.
  • Manage access: Invite users to a space and set their roles, so permissions stay in step with your own systems of record.

The API is available in AWS North America, AWS Europe, Azure North America, and GCP North America. Authenticate with a Contentstack authtoken or an OAuth access token, and pass the x-cs-api-version header with a value of 4 on every request.

We’re looking forward to seeing what you build on it. Check our Assets API documentation for full details.

Note: Assets is a paid add-on and it may not be enabled for your organization. To purchase it, contact our support team.

You can now update the same text across multiple entries in a single operation from the entry list page with Find and Replace. Filter and select your entries, search for a text string, then replace it or remove it in a single operation.

From the entry list page, you can:

  • Match text your way: choose Contains, Matches, or Exactly matches to control how strictly your search term is compared.
  • Replace or remove: enter replacement text, or leave it empty to delete every matching occurrence.
  • Preview before you apply: review each match by entry, locale, and field, including the number of matches and the resulting state, then fine-tune your selection.
  • Add to a release: bundle the successfully replaced entries into a new or existing release for publishing.
Note
  • Each entry is updated in a single operation, it's either fully replaced or fails as a whole, and each change is saved as a new version.
  • Find and replace runs only on text fields, in the branch and locales you select.
  • It respects your permissions, you can only change entries and fields you can edit.
  • Find and Replace is available on select plans. Contact support for more information.

Check our documentation for more details.

New Features:

  • Added publish and unpublish support for taxonomies and terms.
  • Added localize and unlocalize support for taxonomies and terms.

You can now assign names to specific versions of your variant entries, the same way you name versions of a base entry. Naming a version makes it easy to identify a key change or milestone at a glance, instead of scanning version numbers.

With this update, you can:

  • Name an entry variant version directly from the version history; the name is saved without a separate save step.
  • Find the right version faster using meaningful names instead of version numbers.
  • Manage names through the API with new Content Management API calls to set, list, and remove variant version names.

Check our documentation for more details, or contact support for more information.

We've added environment selection to branch creation, so you can choose which environments to clone into a new branch instead of cloning all environments by default.

In the Create New Branch modal, or through the Content Management API, you decide whether a branch clones all environments, none, or a specific set.

When you create a branch, you can:

  • Clone specific environments: Select only the environments the branch needs under Specific, then Select Environments.
  • Clone all or none: Choose All to clone every environment from the source branch, or None to clone no environments.
  • Control cloning from the API: Pass publish_config.environments on the create-branch endpoint to set the same behavior programmatically.

Note
Specific is the default in the UI, so the Create button stays disabled until you select at least one environment. The API differs: it clones all environments by default when publish_config is omitted, so existing integrations are unchanged.

Check our documentation for full details, or contact support for more information.

New Feature:

  • Added Taxonomy CDA support: fetch and query published taxonomies and terms with hierarchy traversal, localization, and fallback.

Contentstack now supports organization-specific HMAC signing for webhook payloads, giving you greater security and control over webhook verification. Contentstack's earlier webhook signing model used one platform-wide certificate across all payloads. HMAC signing gives each organization its own secret key, generated and managed from Administration > Security Configuration > HMAC Signing, and used to sign webhook payloads with the HMAC-SHA256 algorithm.

What's New:

  • Isolated signing keys: Each organization signs with its own secret key, ensuring that keys are isolated across organizations. Consumers can verify that requests originating from Contentstack were not altered in transit.
  • Self-service key rotation: Regenerate your secret key any time directly from the UI, without contacting support.
  • Zero-downtime rotation: When you regenerate a key, choose how long the previous key stays valid, from immediately up to 24 hours. During the grace period, Contentstack signs payloads with both keys so existing consumers continue working while you update them.
  • Per-webhook control: Choose the signing method for each webhook using the new Request Signing Method field to gradually adopt HMAC while other webhooks continue using the default Contentstack certificate.
  • Secure by design: Secret keys are encrypted and are never exposed after creation. Each payload includes a timestamp to help your application detect and reject replayed requests.

Users with the Owner, Admin, Security Manager, or a custom role with the required permissions can enable, regenerate, or disable HMAC signing.

Note: This feature might not be enabled by default. Contact our support team to get it enabled for your organization.

Learn how to enable HMAC signing, rotate your key, and verify signatures in our HMAC Signing documentation.

We’ve added new enhancements to the Brightcove app:

  • Multiple Configuration Support: You can now set up multiple Brightcove accounts using separate configurations.
  • Video ID Search: Search and add videos by video ID directly from the selector page.
  • Advanced Configuration Object: Added support for configuration objects in advanced settings for the Custom and JSON RTE fields for easier setup and management.
    • Branch-specific Configuration Support: Set branch-specific parameters to scope asset selection to a particular branch.
    • Locale-specific Configuration Support: Set locale-specific parameters to tailor asset selection by language.

To learn more, refer to the Brightcove App Installation Guide.

Enhancements:

  • Updated the contentType(...).entry(...).variants(variantUidOrUids, branchName?) method to accept an optional branchName as the second argument, which sets the CMA branch header for that variant's scope. The first argument supports either a single variant UID string or an array of UIDs (comma-separated in the request path). Omitting the branch name preserves the previous behavior.
  • Added variants(uid).publish() and variants(uid).unpublish() methods, which call the entry publish and unpublish endpoints by nesting the variant payload under the entry.
  • Updated the publish() and unpublish() methods (for both entries and entry variants) to accept optional headers and parameters, which are merged directly into the underlying HTTP request.
  • Added unit and sanity API tests for entry variants with an explicit branch, as well as for the new variant publish and unpublish methods.

New Features:

  • Added branch support in entry variants.

Enhancements:

  • Updated the variants() method on Entry and Entries to support an optional branch name as the second argument. When provided, the branch is sent as a request header alongside x-cs-variant-uid.
  • Ensured existing variants(uid) and variants(uids) calls remain backward compatible.
  • Added unit and API tests to support variant and branch requests.

New Features:

  • Added branch support in entry variants.

Enhancements:

  • Added support for entry variants with optional branch scoping via the variants() method on Entry and Query.

Enhancements:

  • Added the variants(variant_uids, branch_name) method to Contentstack::Entry and Contentstack::Query to fetch entry variants with optional per-request branch scoping. These requests now send the x-cs-variant-uid header (as comma-separated UIDs) and respect either the stack-level or per-call branch settings.

Enhancements:

  • Made the launch plugin opt-in, it is no longer bundled with the CLI. Install it using csdx plugins:install @contentstack/cli-launch to use launch commands in CLI (v2.0.0-beta.30).
  • Added the readGlobalFieldSchemas utility function in cli-utilities (v2.0.0-beta.12).
  • Automatically refreshed region configurations set on older CLI versions with the latest endpoint data upon the next command execution, eliminating the need to manually run config:set:region in cli-utilities (v2.0.0-beta.12).
  • Updated the config:set:region command to store the full endpoint set for the selected region, making any future Contentstack endpoints available without requiring a command re-run in cli-config (v2.0.0-beta.15).
  • Switched global fields to a per-file export/import format in the following CLI plugins:
    • cli-export (v2.0.0-beta.25)
    • cli-import (v2.0.0-beta.25)
    • cli-audit (v2.0.0-beta.16)
    • cli-import-setup (v2.0.0-beta.19)
  • Added global field rule handling to content types in cli-import (v2.0.0-beta.25).
  • Added addHeader to the publish-entries chain in cli-import (v2.0.0-beta.25).
  • Enhanced the field rules audit to include global fields in cli-audit (v2.0.0-beta.16).
  • Enhanced Asset Management (AM) with asset publishing support in cli-asset-management (v1.0.0-beta.8).
  • Forced api_version=3.2 on all entry and asset publish/unpublish call sites in the following CLI plugins:
    • contentstack-external-migrate (v2.0.0-beta.4)
    • cli-bulk-operations (v2.0.0-beta.5)
  • Hardened the NRP header on taxonomy publish and fixed include-variants validation in cli-bulk-operations (v2.0.0-beta.5).

Bug & Security Fixes:

  • Reconciled completed progress bar counts with processed items in cli-utilities (v2.0.0-beta.12).
  • Resolved an issue where resolving the org plan or auth host would fail hard when not explicitly configured, and successfully derived it from the existing region host as a fallback in cli-utilities (v2.0.0-beta.12).
  • Fixed context setting issues in cli-command (v2.0.0-beta.11).
  • Fixed an issue to add global fields Field Validation Rules (FVRs) in exports in cli-export (v2.0.0-beta.25).
  • Fixed an issue by collecting all locales and deduplicating asset UIDs in the bulk payload in cli-bulk-operations (v2.0.0-beta.5).
  • Updated dependency versions in the following CLI plugins:
    • cli-auth (v2.0.0-beta.17)
    • cli-command (v2.0.0-beta.11)
    • cli-config (v2.0.0-beta.15)
    • apps-cli (v2.0.0-beta.5)
    • cli-cm-bootstrap (v2.0.0-beta.25)
    • cli-cm-branches (v2.0.0-beta.11)
    • cli-cm-regex-validate (v2.0.0-beta.4)
    • contentstack-cli-tsgen (v5.0.0-beta.4)
    • cli-cm-clone (v2.0.0-beta.26)
    • contentstack-cli-content-type (v2.0.0-beta.3)
    • cli-cm-export-to-csv (v2.0.0-beta.12)
    • cli-cm-migrate-rte (v2.0.0-beta.10)
    • cli-migration (v2.0.0-beta.17)
    • cli-cm-export-query (v2.0.0-beta.9)
    • cli-cm-seed (v2.0.0-beta.25)
    • cli-variants (v2.0.0-beta.20)

Enhancements:

  • CLI (v1.66.0):
    • Added groundwork for organization plan-based feature gating for CLI commands (currently inactive until individual commands opt in).
    • Introduced an auto-refresh for endpoints on command pre-run.
  • Added support for global field validation rule for the following plugins:
    • cli-audit (v1.20.0)
    • cli-export (v1.26.0)
    • cli-import (v1.34.0)
cli-config (v1.22.0):
    Updated the config:set:region command to store the full endpoint set for the selected region. Any future Contentstack endpoint added will now be available without requiring a command re-run.
cli-utilities (v1.20.0):
    Region configurations set on older CLI versions are now automatically refreshed with the latest endpoint data upon the next command execution, eliminating the need to manually run config:set:region.
Updated dependency versions for the following plugins:
    @contentstack/cli-cm-clone (v1.21.10)@contentstack/cli-cm-export-query (v1.0.6)@contentstack/cli-cm-seed (v1.15.9)@contentstack/cli-auth (v1.8.5)@contentstack/apps-cli (v1.7.3)@contentstack/cli-cm-bootstrap (v1.19.8)@contentstack/cli-cm-branches (v1.8.4)@contentstack/cli-cm-bulk-publish (v1.12.2)contentstack-cli-tsgen (v4.10.2)@contentstack/cli-cm-export-to-csv (v1.12.7)@contentstack/cli-external-migrate (v1.0.0)@contentstack/cli-cm-import-setup (v1.8.7)@contentstack/cli-migration (v1.12.5)@contentstack/cli-variants (v1.6.1)

Bug & Security Fixes:

  • cli-utilities (v1.20.0):
    • Resolved an issue where resolving the org plan or auth host would fail hard when not explicitly configured. It now successfully falls back to deriving from the existing region host.
  • cli-command (v1.8.6):
    • Fixed issues related to context setting.
  • Security Fixes: Resolved security vulnerabilities in the following plugins:
    • cli-bulk-operations (v1.2.3)
    • cli-cm-regex-validate (v1.0.2)
    • contentstack-cli-content-type (v1.5.3)
    • cli-cm-migrate-rte (v1.7.3)

We’ve enhanced Live Preview so that teams editing the same entry now share a collaborative draft preview. 

Previously, each user had a separate preview and saw only their own unsaved changes. Now, when multiple users edit the same entry, everyone sees the same content as it changes.

With Collaborative Live Preview, you can:

  • See collaborators’ edits in your preview as they work on the same entry.
  • Stay in sync automatically, your own changes appear instantly, and others’ changes appear after a brief delay, so the preview does not reload on every edit.
  • Preview every field, since collaborative preview applies to all fields in the entry.

Note: Collaborative drafts are not yet available in Visual Editor.

Refer to the Collaborative Drafts in Live Preview documentation for full details, or contact support for more information.

New Features:

  • Added support for passing an optional branch parameter to the .Variant() method in both the Entry and Query classes to support Entry Variants branching.
  • Implemented an automatic fallback to the Stack's configured branch or "main" if the branch parameter is null or empty.
  • Added comprehensive unit and integration tests for the Entry and Query variant branch logic.

New Features:

  • Added optional branch support for entry variants in the Entry.variants() and ContentType.variants() methods.

New Features:

  • Added branch override support for Entry Variants. The Entry.Variant(uid?, branchUid?) method now accepts an optional branchUid to target a specific branch for variant calls (Find, Create, Update, Fetch, Delete) by overriding the branch request header. If null or empty, it falls back to the Stack's configured branch.
  • Added publish and unpublish support for Entry Variants via EntryVariant.Publish/PublishAsync and EntryVariant.Unpublish/UnpublishAsync. These methods match the PublishUnpublishDetails contract used by Entry.Publish/Unpublish and respect the branch override.

New Features:

  • Added publish and unpublish support for Entry Variants via the entry publish/unpublish endpoints, including documented payloads for entry.variants and optional entry.variant_rules on publish.
  • Added optional stack branch support via the branch request header for Entry Variants. Entry.variants() now accepts no arguments, a branch UID only, or (variant_uid, branch) (use variants(variant_uid, None) when targeting a variant without a branch).

New Feature:

  • Added branch support in entry variants.

New Feature:

  • Added branch support in entry variants.

Enhancements:

  • cli-bulk-operations:
    • Merged the cm:stacks:bulk-am-assets command into cm:stacks:bulk-assets. All asset functionality is now supported directly by cm:stacks:bulk-assets, removing the need for a specific assets command.
    • Integrated the Progress Manager UI into all cm:stacks:bulk-* commands, ensuring bulk operations now display a clean header, a live summary, and per-command Module Details.
  • Upgraded dependencies for the following plugins:
    • cli-utilities (v2.0.0-beta.11)
    • cli-bulk-operations (v2.0.0-beta.4)
    • cli-auth (v2.0.0-beta.16)
    • cli-command (v2.0.0-beta.10)
    • cli-config (v2.0.0-beta.14)
    • apps-cli (v2.0.0-beta.4)
    • cli-asset-management (v1.0.0-beta.7)
    • cli-audit (v2.0.0-beta.15)
    • cli-cm-bootstrap (v2.0.0-beta.24)
    • cli-cm-branches (v2.0.0-beta.10)
    • cli-cm-regex-validate (v2.0.0-beta.3)
    • contentstack-cli-tsgen (v5.0.0-beta.3)
    • cli-cm-clone (v2.0.0-beta.25)
    • contentstack-cli-content-type (v2.0.0-beta.2)
    • cli-cm-export (v2.0.0-beta.24)
    • cli-cm-export-to-csv (v2.0.0-beta.11)
    • cli-external-migrate (v2.0.0-beta.3)
    • cli-cm-import (v2.0.0-beta.24)
    • cli-cm-import-setup (v2.0.0-beta.18)
    • cli-cm-migrate-rte (v2.0.0-beta.9)
    • cli-migration (v2.0.0-beta.16)
    • cli-cm-export-query (v2.0.0-beta.8)
    • cli-cm-seed (v2.0.0-beta.24)
    • cli-variants (v2.0.0-beta.19)

New Feature:

  • Added support for Taxonomy Localization and Publishing.

Enhancement:

  • Removed the locale parameter from Taxonomy.fetch() and Term.fetch().

New Feature:

  • Added Taxonomy Publishing support to the Content Delivery SDK via stack.taxonomy().

Lytics CDP is now available from the App Switcher in your Contentstack organization. It's Contentstack's interface for managing behavioral data collection, audience building, and personalization activation across your digital properties, all connected directly to your CMS, Launch, and Personalize projects.

With Lytics CDP, you can:

  • Collect behavioral data automatically: Install the JStag SDK on your front end, or enable it with a single toggle if your site runs on Contentstack Launch, to start capturing visitor events across web, mobile, and other digital touchpoints.
  • Connect your Contentstack products in one place: Link your CMS stacks, Launch projects, and Personalize projects to a Lytics project so audience data flows automatically, with no custom middleware or data pipelines required.
  • Activate real-time personalization: Use live visitor behavior and audience membership, authored on the Lytics platform, to determine which content variant a visitor receives in Personalize.
  • Manage everything at the project level: Create and manage Lytics projects, collaborators, and connections directly in Contentstack, with access controlled through your existing organization roles.

Lytics CDP works alongside the Lytics platform (app.lytics.com), where audience authoring, profile inspection, and data pipeline configuration still happen. You can jump straight into the Lytics platform from your project dashboard using the Manage Lytics button and single sign-on.

If you previously connected Lytics through the Data Activation Layer (DAL), your existing configuration, data, users, and settings have been automatically converted into a Lytics CDP project, and your Lytics audiences continue to work in Personalize without any changes.

What's New?

  • Stack-Aware Tool Enrichment: Enabled by default, tool descriptions, enums, defaults, and argument guidance are now tailored to your connected Contentstack stack.
    • Enrichment support across CDA, CMA, CMA Extended, Launch, Brand Kit, Personalize, and Developer Hub tools
    • New x-enrich, x-enrich-group, and x-enrich-description metadata added to tool definitions, plus a machine-readable tools/enrich-profiles.json reference
    • CONTENTSTACK_MCP_ENRICH_TOOLS=false available to disable enrichment while still stripping raw enrichment metadata from exposed tool schemas
    • Optional stack context inputs: CONTENTSTACK_ENVIRONMENT, CONTENTSTACK_BRANCH, and CONTENTSTACK_LOCALE
  • Taxonomy Term Reordering and Reparenting: A new move_a_term tool in the CMA group supports reordering and reparenting a taxonomy term via PUT /v3/taxonomies/{taxonomy_uid}/terms/{term_uid}/move. Previously, update_a_term only supported renaming — hierarchy changes were not possible through the server.
  • Tool-Selection Evaluation Harness: A new OpenAI evaluation harness under eval/ measures MCP tool-selection behavior with enriched tool definitions.
  • To learn more, refer to the Contentstack MCP Server documentation.

New Features:

  • Added Branch management with Create, Fetch, Delete (including Async variants), and Query operations via Stack.Branch(uid?).
  • Introduced multi-region endpoint resolution via Endpoint.GetContentstackEndpoint(region, service) supporting 7 regions (NA, EU, AU, Azure-NA, Azure-EU, GCP-NA, GCP-EU) and 18 service keys.
  • Wired OAuth auto token refresh into the request pipeline.
  • Added PreviewToken support for Create and Delete operations.
  • Added image format upload coverage for JPEG, AVIF, and multi-format assets.

Enhancements:

  • Upgraded the framework requirement to .NET 10 or later.
  • Removed the Newtonsoft.Json dependency; all JSON serialization now uses System.Text.Json.
  • Replaced client.SerializerSettings (JsonSerializerSettings) with client.SerializerOptions (JsonSerializerOptions).
  • Removed response.OpenJObjectResponse() in favor of response.OpenJsonObjectResponse() (JsonObject) or response.OpenTResponse<T>().
  • Updated JObjectParameterValue to accept System.Text.Json.Nodes.JsonNode instead of Newtonsoft.Json.Linq.JObject.
  • Replaced all [JsonProperty] attributes with [JsonPropertyName].

New Features:

  • Added support for the GCP_EU region.
  • Added the Endpoint class for dynamic region-to-URL resolution via CDN-backed regions.json, and ContentstackRegionMap to map the ContentstackRegion enum to registry region IDs.
  • Added ApiErrorBodyParser for consistent API error envelope parsing.
  • Added JsonNodeConversion and JsonObjectMerge utilities to replace Newtonsoft equivalents.
  • Added ContentstackJsonDefaults to provide shared JsonSerializerOptions across all custom converters.

Enhancements:

  • Upgraded the framework requirement to .NET 10 or later.
  • Removed the Newtonsoft.Json dependency; all JSON serialization now uses System.Text.Json (BCL).
  • Migrated SDK methods to use JsonObject instead of JObject. Entry.ToJson(), Query.Count(), AssetLibrary.Count(), ContentType.Fetch(), GlobalField.Fetch(), and GlobalFieldQuery.Find() now return JsonObject.
  • Updated AssetLibrary.Query() to accept JsonObject as its parameter.
  • Replaced SerializerSettings with SerializerOptions and updated model classes to use [JsonPropertyName] instead of [JsonProperty].
  • Updated Config.BaseUrl to resolve hosts from the regions registry, removing the hardcoded regionCode() and HostURL.
  • Replaced Console.WriteLine with Debug.WriteLine in ContentstackConvert to suppress parse warnings from the application stdout.
  • Updated the contentstack.utils dependency to v2.0.0 (final release).
  • Replaced refresh-region.cs with refresh-region.py to prevent MSBuild from compiling the script as source, and added build/contentstack.csharp.targets to auto-deliver the script to consumer projects on their first build.
  • Updated the .NET version in the SCA scan CI pipeline from 7.0.x to 10.0.x.
  • Added EndpointTest.cs and added Assets/regions.json to .gitignore.

New Features:

  • Introduced multi-region endpoint resolution via Endpoint.GetContentstackEndpoint(region, service), supporting 7 regions (NA, EU, AU, Azure-NA, Azure-EU, GCP-NA, GCP-EU) and 18 service keys.
  • Added a proxy method Utils.GetContentstackEndpoint(region, service) to access endpoint resolution directly from the Utils class without needing to import Contentstack.Utils.Endpoints.
  • Added the omitHttps flag to strip the https:// scheme from returned URLs, allowing for direct passing to SDK host configurations (e.g., new ContentstackOptions { Host = Endpoint.GetContentstackEndpoint("eu", "contentDelivery", omitHttps: true) }).
  • Added case-insensitive region alias support (e.g., "us", "NA", "AWS-NA", and "azure_na" all resolve correctly to the same region).
  • Implemented an auto-download and disk caching mechanism for the regions.json registry from the CDN on first use, requiring no setup. The SDK self-heals if the file is missing.
  • Bundled Scripts/refresh-region.py inside the NuGet package, which automatically places the script in your project's Scripts/ folder upon the first dotnet build. You can run this script anytime to pull the latest regions from the CDN.

Breaking Changes:

  • Upgraded the framework requirement to .NET 10 or later (previously netstandard2.0 / net6.0).
  • Removed the Newtonsoft.Json package reference and replaced it with System.Text.Json across the entire package. Consuming projects must add System.Text.Json or rely on the BCL on supported runtimes.
  • Updated GetVariantAliases() and GetVariantMetadataTags() methods to accept JsonObject / JsonArray instead of JObject / JArray.
  • Deprecated GetDataCsvariantsAttribute(JObject/JArray, string), which now maps to JsonObject / JsonArray overloads.
  • Updated Node.attrs values to use System.Text.Json.JsonElement instead of Newtonsoft.Json.Linq.JToken. (Note: Consuming code should update from node.attrs["src"].Value<string>() to node.attrs["src"].GetString()).
  • Updated model classes to use [JsonPropertyName] instead of [JsonProperty].

Enhancements:

  • Upgraded the target framework requirement to .NET 10.0 or later (previously .NET 7.0).
  • Removed the Newtonsoft.Json dependency entirely. Migrated the tool's internals, model DTOs, OAuth service, the HTTP layer, and ContentstackClient to use System.Text.Json.
  • Updated code-generation templates so that generated model files now use [JsonPropertyName] and generated converters inherit System.Text.Json.Serialization.JsonConverter<T>.

Note: Regenerating models against an existing project will change these attributes and converters, so consuming code must be updated accordingly.

  • Removed support for legacy BinaryFormatter-based serialization in ContentstackException.
  • Updated reference-field type resolution to use System.Text.Json.JsonElement instead of the removed Newtonsoft types.
  • Updated the CI/CD pipeline to use the .NET 10 SDK and upgraded Microsoft.AspNetCore.Mvc.Testing to version 10.0.0.

Bug & Security Fixes:

  • Fixed a template bug where the generated embeddedItems property's nullable annotation was incorrectly emitted as literal text ({nullableString()}) for content types with RTE-embedded references.
  • Fixed the GetHeader method visibility (changed from private to internal) to allow test access.

Managing multiple personalization experiences across campaigns, audiences, and content types can get complex fast. Experience Tags give you a flexible, searchable way to label, group, and filter your experiences in Personalize, so your team always knows what's running, why it exists, and where it belongs.

You can now create custom tags and attach them to any experience directly from the Personalize dashboard. Use tags to reflect your internal taxonomy, whether that's by region, campaign type, audience segment, lifecycle stage, or any other dimension that matters to your team.

With Experience Tags, you can:

  • Stay organized at scale: Filter your experience list by one or more tags instantly. No more scrolling through dozens of experiences to find what's relevant.
  • Apply multiple tags per experience: Support cross-functional views - for example, tag an experience as both "Holiday 2026" and "EMEA" simultaneously.
  • Standardize naming across your team: Reuse tags created by any team member in the same project to keep your taxonomy consistent.
  • Audit and govern with ease: Use tags as a lightweight governance layer when many experiences are running in parallel across teams or campaigns.

Additional Resources:

We have released Contentstack MCP Server v0.7.3, a fix for an issue affecting MCP clients that skip the tools/list step.

What's New?

  • Added automations tool group with 9 tools: list_automation_projects, get_automation_project, create_automation_project, update_automation_project, delete_automation_project,list_automations, get_automation, trigger_automation, set_automation_active
  • Added CONTENTSTACK_AUTOMATIONS_BASE_URL for dedicated automations infrastructure overrides

What's Fixed?

  • Fixed server startup failure when invoked via npx @contentstack/mcp, caused by unresolved symlinks in entrypoint detection

To learn more, refer to the Contentstack MCP Server documentation.

Enhancements:

  • Upgraded dependencies for the following plugins:
    • cli-cm-clone (v2.0.0-beta.23)
    • cli-cm-seed (v2.0.0-beta.22)
    • cli-cm-export-query (v2.0.0-beta.6)
    • cli-cm-bootstrap (v2.0.0-beta.22)
    • cli-cm-import-setup (v2.0.0-beta.16)
  • Improved API key validation in cli-cm-export (v2.0.0-beta.22).
  • Updated and removed short flags across the following plugins:
    • apps-cli (v2.0.0-beta.2)
    • contentstack-cli-tsgen (v5.0.0-beta.2)
    • cli-external-migrate (v2.0.0-beta.1)
    • cli-migration (v2.0.0-beta.15)
    • cli-cm-regex-validate (v2.0.0-beta.2)
    • cli-auth (v2.0.0-beta.15)
    • cli-config (v2.0.0-beta.13)

Bug & Security Fixes:

  • Fixed an issue to ensure login errors are displayed on the console and improved core API key validation.
  • Fixed an issue to successfully display the backup folder path upon command completion.
  • Fixed and improved API key validation specifically in cli-cm-import (v2.0.0-beta.22).

We’ve added branch support for Variants, so you can build and test personalized content in an isolated branch before making it available on your main branch. Entry variants are no longer limited to the main branch.

You can now:

  • Manage variant configuration on any branch: link content types and create entry variants in a development branch, isolated from main.
  • Keep variant groups consistent: a variant group and its variants stay global across branches, while content type assignment and entry variants remain branch-specific.
  • Test personalization in isolation: onboard to Personalize or run an A/B test without affecting production content on main.
  • Merge variant groups across branches: merge variant group configuration from a compare branch into a base branch using the Content Management API, with five merge strategies.

Note: Merging variant groups is available through the API. Workflow status is not included in the merge.

Check our documentation for full details, or contact support for more information.

We are excited to announce the MCP Client tool in Agent OS Agents, enabling you to connect your agents to any remote Model Context Protocol (MCP) server and use its tools automatically, no custom integration code required.

MCP Client Tool: A new tool available in the Agent OS agent builder that connects your agent to any remote MCP server over HTTPS.

  • Connect once and your agent gains access to all tools the server exposes, or the specific subset you approve.
  • Support for two authentication methods: Header-based authentication (API key or token) and OAuth 2.1 (sign-in via provider consent screen).
  • OAuth supports both automatic setup via Dynamic client registration and manual setup for providers that require a registered OAuth app.
  • Allowed Tools selector lets you either allow the AI to choose freely from all available tools, or lock it down to only the specific tools you pick.
  • Connections are reusable, a saved MCP Client connection can be attached to multiple agents from the Connected Apps page.

To learn more, refer to the MCP Client: Connect Remote Tools documentation.

Entries that use custom URL patterns now resolve in Visual Editor the same way they do in Live Preview, using the same configuration with no additional setup.

With this update, you can:

  • Preview custom URL entries directly on the Visual Editor canvas.
  • Browse pages from custom URL content types in the URL bar, with each entry’s resolved URL shown.
  • Create pages for custom URL content types without a URL field.
  • Resolve missing values from a screen that lists the fields a pattern needs, with a link to each field in the form.

For sites that use custom URLs, developers set the page context (Live Preview Utils SDK 4.4.4 or later) so the Start editing button opens the correct entry. See the SDK config reference for implementation details.

Note: Custom Preview URLs is available on select plans.

Learn more in the documentation, or contact support for more information.

Here’s an overview of the latest updates in Contentstack Launch:

  • Response Mode Selection for Environments:

    You can now choose how your environment delivers responses with the new Response Mode setting — Streaming, which delivers response chunks in real time as they are generated, or Buffered, which displays output only after the entire response has been generated. This replaces the earlier Enable Streaming Responses toggle, giving you explicit control over response delivery and making the default behavior (Buffered) visible at a glance. A Response Mode column is now available in the Environments list table, letting you view each environment's response mode at a glance.

    Learn more in Environments.

  • Project and Environment Selection in Log Targets:

    You can now select specific project and environment combinations when setting up a Log Target, and choose which type of logs — Server Logs, Traffic Logs, or both — to forward to each destination. Alternatively, you can choose to export logs for all current and future projects and environments within your organization. This gives you precise control over what data reaches each monitoring destination, reducing noise and keeping observability costs in check.

    Learn more in Log Targets.

Enhancements

  • Node.js 22 Runtime Migration: Upgraded the Node.js runtime version to v22 across all CLI plugins and updated the corresponding documentation.
  • ESLint Infrastructure Upgrade: Upgraded ESLint to v10.50.0 and migrated all plugin configurations to the new flat config format.
  • Dependency and Plugin Updates: Rolled out the runtime and linting enhancements across the following plugin versions:
    • cli-audit v1.19.5
    • cli-cm-export v1.25.2
    • cli-cm-import v1.33.4
    • cli-auth v1.8.4
    • cli-cm-bootstrap v1.19.7
    • cli-cm-branches v1.8.3
    • cli-cm-bulk-publish v1.12.1
    • cli-cm-clone v1.21.8
    • cli-cm-export-to-csv v1.12.5
    • cli-cm-import-setup v1.8.5
    • cli-cm-migrate-rte v1.7.1
    • cli-cm-seed v1.15.7
    • cli-command v1.8.4
    • cli-config v1.20.5
    • cli-migration v1.12.4
    • cli-utilities v1.18.5
    • apps-cli v1.7.1
    • cli-bulk-operations v1.2.1
    • cli-cm-regex-validate v1.0.1
    • contentstack-cli-tsgen v4.10.1
    • contentstack-cli-content-type v1.5.1
    • cli-external-migrate v1.0.0-alpha.4
    • cli-cm-export-query v1.0.4

Bug Fix

  • Organization User Pagination: Resolved pagination bugs within the organization user fetch logic (cli-cm-export-to-csv v1.12.4).

Enhancements

  • New Plugin Integration: Introduced the contentstack/cli-external-migrate plugin (cli-external-migrate v2.0.0-beta.0) into the ecosystem.
  • Node.js 22 Runtime Migration: Upgraded the Node.js runtime version to v22 across beta plugins and updated the corresponding documentation.
  • ESLint Infrastructure Upgrade: Upgraded ESLint to v10.50.0 and migrated plugin configurations to the new flat config format.
  • Beta Plugin Dependency Updates: Rolled out runtime and linting enhancements across the following beta plugin versions:
    • cli-audit v2.0.0-beta.14
    • cli-cm-export v2.0.0-beta.21
    • cli-cm-import v2.0.0-beta.21
    • cli-auth v2.0.0-beta.14
    • cli-cm-bootstrap v2.0.0-beta.21
    • cli-cm-branches v2.0.0-beta.9
    • cli-cm-bulk-publish v2.0.0-beta.2
    • cli-cm-clone v2.0.0-beta.22
    • cli-cm-export-to-csv v2.0.0-beta.9
    • cli-cm-import-setup v2.0.0-beta.15
    • cli-cm-migrate-rte v2.0.0-beta.8
    • cli-cm-seed v2.0.0-beta.21
    • cli-command v2.0.0-beta.9
    • cli-config v2.0.0-beta.12
    • cli-migration v2.0.0-beta.14
    • cli-utilities v2.0.0-beta.10
    • apps-cli v2.0.0-beta.1
    • cli-bulk-operations v2.0.0-beta.2
    • cli-cm-regex-validate v2.0.0-beta.1
    • contentstack-cli-tsgen v5.0.0-beta.1
    • contentstack-cli-content-type v2.0.0-beta.1
    • cli-cm-export-query v2.0.0-beta.5

Enhancement

  • Dynamic Region Endpoint Resolution: Introduced Endpoint.getContentstackEndpoint to dynamically resolve service endpoints from the centralized Contentstack Regions Registry. This implementation features alias-aware, case-insensitive evaluation and throws an explicit Endpoint.EndpointError upon encountering invalid input.

New Features

  • Dynamic Region Endpoint Resolution: Introduced ContentstackUtils::Endpoint.get_contentstack_endpoint to enable dynamic URL routing based on specified region and service configurations.
  • Endpoint Resolution Proxy: Added ContentstackUtils.get_contentstack_endpoint as a top-level module proxy to maintain backward compatibility with existing integration patterns.
  • Automated Runtime Fallback: Integrated a runtime synchronization mechanism that automatically downloads the regions.json manifest from the Contentstack Regions Registry if the file is not present in the local cache.
  • Manual Registry Synchronization: Added ContentstackUtils::Endpoint.refresh_regions to facilitate the manual retrieval and refreshing of localized region metadata.

Security and Bug Fixes

  • Dependency Vulnerability Patches: Upgraded critical project dependencies to resolve established security risks:
    • Upgraded yard to 0.9.44 to address a Directory Traversal vulnerability.
    • Upgraded concurrent-ruby to 1.3.7 to fix issues relating to infinite loops, improper locking, and wrap-around errors.

New Features

  • Dynamic Region Endpoint Resolution: Introduced Endpoint.getContentstackEndpoint() to enable dynamic service URL routing driven by the centralized Contentstack Regions Registry.
  • Endpoint Resolution Proxy: Added Utils.getContentstackEndpoint() as a top-level proxy method to ensure backward-compatible access through the existing utility path.
  • Automated Registry Provisioning: Integrated a dual-phase registry mechanism where regions.json is automatically downloaded at build time via scripts/download-regions.sh, supplemented by a fail-safe runtime fallback to fetch the manifest if the local file is missing.

Enhancement

  • Dynamic Region Endpoint Resolution: Implemented dynamic endpoint routing powered by the centralized Contentstack Regions Registry. Developers can now utilize Endpoint.getContentstackEndpoint() and the configured Builder.setRegion() mechanism to resolve service URLs automatically across all supported environments.

Enhancements

  • Dynamic Region Endpoint Resolution: Implemented dynamic endpoint routing powered by the centralized Contentstack Regions Registry. Developers can now utilize Endpoint.getContentstackEndpoint() and the configured Builder.setRegion() mechanism to resolve service URLs automatically across all supported environments.

What's New?

We are excited to announce Contentstack MCP Server v0.7.2, introducing OAuth scope declarations across all 196 tools in the nine /<group>/tools endpoints, giving the served JSON a single source of truth for tool-to-scope mappings used by the OAuth consent flow and runtime authorization.

Each tool entry now includes a scopes array alongside group, making the served JSON the authoritative source for the tool-to-scope mapping consumed by the OAuth consent flow and runtime authorization checks. Scopes are derived deterministically from (group, mapper.method, mapper.apiUrl, name) via src/utils/scopes.ts; run npm run generate:scopes to regenerate them as needed. Note that cda and lytics resolve to an empty array ([]), since these use delivery-token and Lytics-token authentication rather than OAuth.


This release includes two improvements to the entry editing experience.

Regex Validation for URL fields

You can now apply the Validation (Regex) and Validation Error Message properties to URL fields to control the URL format that content managers can enter. Previously, these options were available only for Single Line Textbox and Multi Line Textbox fields. With this change, you can:

  • Define a custom regex pattern for the accepted URL format.
  • Show a custom validation message when an entered value doesn't match the pattern.

Refer to the URL field documentation for details.

Live Preview Panel Now Stays Open in the Entry Editor

The Live Preview panel now follows the standard entry editor panel behavior, making navigation more predictable as you work across entries. The panel now:

  • Stays open when you navigate between entries.
  • Preserves its state during entry navigation within your session.
  • Remembers a custom width and restores it when you open later entries.

This reduces the need to reopen or resize the Live Preview panel as you move between multiple entries.

Refer to the Live Preview documentation for details.

We’re adding enhancements to the Algolia app:

  • Multiple Environment and Branch Support: Mapping rules can now be scoped to specific environments and branches. Multiple rules for the same environment are identified by different labels.
  • Content Type Level Index Mapping: Index mapping is now configured one content type at a time, with an explicit index required for each rule.
  • Enhanced Field Level Mapping: Field-level mapping now supports environment and branch-level filtering. Leaving the dropdowns empty defaults to all environments and all branches.

To learn more, refer to the Algolia App Installation Guide.

The Bulk Translate and Content Types Bulk Translate options in the XTM Full Page app now include a Source Language dropdown. You can now select any stack language as the source for translation, instead of being restricted to the stack language. By default, the master language is pre-selected.

To learn more, refer to the XTM App Installation Guide.

New Features

  • Dynamic Region Resolution: Introduced an Endpoint class to enable dynamic region-to-URL resolution utilizing a CDN-backed regions.json file.
  • Region Mapping: Added ContentstackRegionMap to map the ContentstackRegion enum directly to registry region IDs.
  • GCP EU Support: Expanded infrastructure support to include the GCP_EU region.

Enhancements

  • Dynamic Base URL Configuration: Updated Config.BaseUrl to resolve hosts dynamically via the regions registry, removing the hardcoded regionCode() and HostURL logic.
  • Region Refresh Script Migration: Replaced refresh-region.cs with a Python implementation (refresh-region.py) to prevent MSBuild from incorrectly compiling the script as source code.
  • Build Targets Automation: Added build/contentstack.csharp.targets to automatically package and deliver the refresh-region.py script to consumer projects upon their first build.
  • Automated Test Coverage: Implemented EndpointTest.cs to ensure the reliability and coverage of the new endpoint resolution logic.

New Features

  • Dynamic Region Resolution: Introduced an Endpoint class to enable dynamic region-to-URL resolution utilizing a CDN-backed regions.json file.
  • Region Mapping: Added ContentstackRegionMap to map the ContentstackRegion enum directly to registry region IDs.
  • GCP EU Support: Expanded infrastructure support to include the GCP_EU region.

Enhancements

  • Dynamic Base URL Configuration: Updated Config.BaseUrl to resolve hosts dynamically via the regions registry, removing the hardcoded regionCode() and HostURL logic.
  • Region Refresh Script Migration: Replaced refresh-region.cs with a Python implementation (refresh-region.py) to prevent MSBuild from incorrectly compiling the script as source code.
  • Build Targets Automation: Added build/contentstack.csharp.targets to automatically package and deliver the refresh-region.py script to consumer projects upon their first build.
  • Automated Test Coverage: Implemented EndpointTest.cs to ensure the reliability and coverage of the new endpoint resolution logic.

New Features

  • Dynamic Region Resolution: Introduced Endpoint.get_contentstack_endpoint() to enable dynamic, region-aware URL resolution across all supported Contentstack regions and services.
  • Endpoint Resolution Proxy: Added Utils.get_contentstack_endpoint() as a top-level proxy method to ensure backward-compatible access via the existing Utils import path.
  • Cross-SDK Parity Aliases: Added getContentstackEndpoint camelCase aliases to both the Endpoint and Utils classes for consistent interface parity across different Contentstack SDKs.
  • Automated Registry Provisioning and Fallback: Bundled the authoritative regions.json registry file (supporting 7 regions and 18 service endpoint keys) into contentstack_utils/assets/regions.json. Implemented a runtime fallback mechanism in Endpoint._load_regions() that automatically downloads the registry from the Contentstack artifact server on first use if the local file is missing.
  • Programmatic and CLI Registry Synchronization: Added a refresh_regions() utility—exposed at the package level—and a python3 -m contentstack_utils.region_refresh CLI command to allow developers to programmatically or manually fetch the latest regions manifest from the CDN and overwrite the local cache.

Enhancements

  • Package-Level Exports: Exposed the Endpoint class within the package-level __all__ export list for simplified imports.
  • Automated Build-Time Refresh: Updated setup.py with a custom BuildPyWithRegions command to automatically refresh regions.json at build time. Network failures during this step are captured as warnings and will not block the build process.
  • Package Data Distribution: Added assets/regions.json to the package_data configuration in setup.py, ensuring the registry file is correctly bundled and shipped within the source distribution and wheel formats.
  • Source-Tree Utility: Bundled scripts/refresh_regions.py into the source tree for standalone environment utilization.

Gain deeper visibility into your Contentstack activity with Log Targets within Administration, a powerful new feature that lets you seamlessly export system-generated logs to your own cloud storage. Whether you're monitoring activity, ensuring compliance, or integrating with observability tools, Log Targets gives you full control over your log data.

Key Features

  • Flexible Log Exporting: Export key system logs, including audit, published, and webhook logs, directly to your preferred cloud storage for centralized monitoring and analysis.
  • Multi-Cloud Support: Connect with leading cloud providers like AWS S3, Azure Blob Storage, and Google Cloud Storage to store and manage your logs securely.
  • Automated Scheduling: Set up hourly export schedules to ensure your logs are consistently updated without manual intervention.
  • Customizable Storage Structure: Define base paths within your storage buckets to organize logs efficiently by type or use case.
  • Improved Visibility with History Tracking: Monitor export activity through a detailed history view, including status, duration, and error reporting for better troubleshooting.

With Log Targets, you can extend Contentstack logging capabilities beyond the platform and into your existing workflows, making observability, auditing, and analysis more streamlined than ever.

Check our documentation for full details, or contact support to get started immediately.

You can now roll back a deployed release in Contentstack to quickly recover from unintended deployments.  If a release is deployed to the wrong environment or publishes content before it is ready, create a rollback release or a duplicate of the deployed release, and deploy it to restore entries and assets to the version published before deployment.

Release Rollback provides a fast, predictable way to recover from publishing mistakes without manually restoring content. It reverts references and assets along with entries, and unpublishes documents that had no previous published version, so the environment returns to its last known good state in a few steps.

Refer to the Roll Back a Release documentation for more information.

We’ve added taxonomy-based filtering to the Select Entries modal used by Reference fields and embedded references in the Rich Text Editor fields. The modal now supports filtering using the existing Taxonomy column.

You can now:

  • Filter entries by one or more taxonomy terms directly in the Select Entries modal.
  • Find relevant entries faster in large content sets.

Note This brings the Select Entries modal in line with the taxonomy filtering already available on the Entry List page.

We are excited to announce Contentstack MCP Server v0.7.0, introducing a new CMA Extended tool group and comprehensive Contentstack MCP Server documentation.

What’s New?

CMA Extended: A new group of 22 tools that extends core CMA functionality with advanced administrative and governance operations.

  • Audit log access and inspection
  • Entry and asset version history
  • Global field creation and updates
  • Asset folder management
  • Workflow and publish rule inspection

Contentstack MCP Server Documentation: A new guide is now available, covering:

  • Setup, authentication, and configuration
  • All API groups and tools
  • Common workflows and best practices
  • Troubleshooting and reference documentation

To learn more, refer to the Contentstack MCP Server documentation.

Gain a clearer, more actionable view of your organization’s security posture with the new Security Dashboard. Designed for admins and security-focused roles, this feature brings critical insights, activity tracking, and recommendations into a single, streamlined interface, helping you proactively manage risks and strengthen compliance.

Security Dashboard.png

Key Features

  • Security Dashboard Overview: Access a dedicated dashboard that replaces basic organization info for elevated roles, providing a unified view of security metrics, risks, and activity.
  • Current Trends Snapshot: Monitor key metrics like total users, inactive accounts, pending invitations, and users without MFA to quickly identify potential vulnerabilities.
  • Security Scorecard: Understand your organization’s security posture with a dynamic score (Critical, At Risk, Secure) based on weighted controls like SSO, MFA, and session policies.
  • Role Distribution Insights: Visualize how roles are assigned across your organization to prevent over-allocation of privileged access.
  • Password Compliance Tracking: Identify users with outdated passwords through categorized timelines, enabling better enforcement of password policies.
  • User Session Insights: Track active sessions, including long-lived sessions (60+ days), to reduce exposure from unattended logins.
  • Recent Activity Feed: Audit security-related events such as user changes, role updates, MFA resets, and configuration changes with severity indicators.

Stay ahead of potential threats with smarter visibility and actionable insights. The Security Dashboard empowers your team to continuously strengthen security and confidently manage your organization at scale.

Read our documentation for more information.

Unified role-based access control (RBAC) introduces finer control over who can administer an organization and what they can do within each product, two new Administration roles, and the ability to create custom roles per product.

Key Features

  • Redesigned user invite interface: Managing users and roles now happens in a completely redesigned interface that brings inviting users, assigning organization-level and product-level roles, and reviewing access into one consistent experience. The same experience extends to SSO identity provider role mapping, SCIM group-to-role mapping, and Teams.
  • New Administration roles: Two out-of-the-box roles join Owner, Admin, and Member at the organization level:
    • Security Manager: Manages an organization's identity and security configuration, including SSO, SCIM provisioning, security settings, and webhooks, with read-only visibility into users, roles, and teams. This removes the previous dependency on the Owner role for configuring SSO.
    • Product Analytics Viewer: Previously, viewing Analytics required Owner or Admin role access. This new role provides read-only access to organization information and analytics, without the ability to change settings or manage users.
  • Multi-role support: Users can now hold multiple organization-level roles at once. For example, a user can be both a Member and a Product Analytics Viewer without requiring elevated admin privileges.
  • Granular product-level permissions: RBAC now scopes access within each product, not only across the organization. Administrators can assign different levels of access per product, such as Administration and Assets, so each user receives precisely the access required for their tasks.
  • Custom roles per product: When the default roles do not match a team's responsibilities, administrators can create custom organization-level roles for a product in Administration by selecting permission categories and actions such as View, Create, Edit, and Delete.

What's Next for RBAC

This release is the first step in a broader rollout. Contentstack is extending RBAC adoption across the platform, with significant enhancements to CMS RBAC coming next, bringing the same granular, consistent access control to stacks and content management.

To learn more about Administration roles, product roles, and creating custom roles, refer to the documentation.

The Contentstack migration framework now supports Drupal as a legacy source and introduces single sign-on (SSO) authentication to the migration framework.

Key Enhancements:

  • Drupal support: Migrate content from Drupal 8, 9, 10, and 11 into a Contentstack stack using the migration framework workflow. Connect your Drupal MySQL database, validate the connection, select your destination stack, and map your content types during migration.
  • Asset migration from Drupal: Move images and media assets alongside your content by providing the base site URL and public asset path of your Drupal site during setup.
  • Flexible content-type mapping: Use the structure detected from your Drupal data as-is, or map Drupal content types to existing content types in your destination stack when you've already modeled your content in Contentstack.
  • Single sign-on (SSO) authentication: Authenticate the migration framework using OAuth 2.0. The tool requests only the permissions required to migrate content, keeping the access granted narrowly scoped to the task.

Note Drupal 7 is not supported. Drupal 7 has reached the end of life and is deprecated by the Drupal community.

For installation and setup, refer to the Migration Tool Setup Guide (Drupal) and the Authenticating the Migration Tool via SSO guide.

We are excited to announce the new Agent OS framework, featuring Agents and Polaris, and the launch of AI Credits. This update provides a more flexible and scalable way to manage and deploy artificial intelligence capabilities across your organization.

What’s New?

  • Agent OS (Agents & Polaris): Step into the next generation of automation with Agent OS.
    • Agents: Deploy autonomous, task-oriented AI agents designed to handle complex workflows with minimal oversight.
    • Polaris: Meet your new platform-wide chat assistant. Polaris is integrated across the entire ecosystem to provide instant support, answer queries, and help you perform AI tasks across your content.
  • AI Credits: We’re introducing a unified credit system to power your AI operations. This simplified consumption model provides greater visibility and control over your AI usage, ensuring your teams monitor and manage credits more effectively.
  • Analytics: To help monitor usage and performance trends, dedicated analytics dashboards are now available for Agents, Polaris, and AI Credits.

This release transforms how organizations access, manage, and scale AI capabilities with centralized controls, intelligent automation, and enterprise-ready experiences.

To learn more, refer to the Agent OS and AI Credits documentation.

We've introduced two enhancements that help you manage entry relationships and URL structures more efficiently while working in Contentstack.

Configure Default URL Patterns for URL Fields

Note: URL pattern configuration and advanced formatting options are available only with URL Management V2. Contact our support team to enable this feature.

You can now configure default URL patterns for URL fields while creating or editing content types.

With URL pattern configuration, you can:

  • Define consistent URL structures using static paths and dynamic placeholders
  • Use supported system fields, custom text fields, locales, and taxonomies in URL patterns
  • Automatically generate localized and structured entry URLs
  • Apply formatting rules such as casing, word separators, JSON mappings, fallback values, and regex transformations
  • Reduce manual URL creation errors and maintain consistent URL structures across entries

For example, you can define a pattern such as /blog/:locale/:field[title] to automatically generate localized blog URLs.

Refer to our documentation to learn how to configure URL patterns and formatting options.

Open Referenced Entries in a Sliding Panel

You can now open referenced entries in a sliding panel within the entry editor. Click the new Open in overlay icon next to a reference to view it without leaving the current page. You can also navigate deeper by opening up to five additional referenced entries in stacked panels and use breadcrumbs to switch between them.

This update reduces the need to open multiple browser tabs when working with nested references, making it easier to validate content relationships or make quick edits without losing your place.

Refer to the documentation on navigating referenced entries.

Note: This feature is plan-based and available to early access customers. Contact support to request access.

You can now publish entries in Contentstack with greater confidence and control with enhanced reference validation and preview workflows. The updated publishing experience helps you review, validate, and selectively publish referenced content before it enters the Publish Queue, reducing errors and rework.

What's New?

  • Review referenced content before publishing
    Use the Publish Review modal to review the parent entry and all associated references to understand what is published before content enters the Publish Queue.
  • Validate references before publishing
    Validate referenced entries and assets using the Validate Items modal to catch issues early and prevent publish failures.
  • Filter and select references precisely
    Choose to publish only the parent entry, specific references, first-level references, or all references to gain greater control over what goes live.
  • Monitor validation and publish progress
    Track validation tasks and publishing status through task windows to maintain visibility and confidence throughout the publishing process.

For more details, visit our documentation or contact our support team.

We are expanding the power of Automations by introducing real-time triggers for our most popular connectors. This update transforms your static workflows into reactive, event-driven systems that respond instantly to external actions.

New Connector Triggers

Our existing connectors for Cloudinary and Netlify have been updated with new trigger options to help you automate your media, deployment, and communication pipelines.

  • Cloudinary: Automate your digital asset management by triggering workflows based on any changes within your Cloudinary environment. Supported events include asset uploads, metadata modifications, folder creation, access control shifts, etc. Learn more about Cloudinary Trigger.
  • Netlify: Keep your development and content teams in sync with your deployment pipeline. You can now trigger automations when builds start, deployments are created, or when environments are locked or unlocked due to permission or configuration issues. Learn more about Netlify Trigger.

Navigation Updates

To support the continued expansion of our platform, we’ve streamlined the project navigation for a more scalable and organized experience.

Settings-related options are now consolidated within the Settings panel in the top navigation, making configuration and operational controls easier to access and manage.

You can now find the following under Settings:

  • Connected Apps
  • Audit Log
  • Execution Log
  • Project Variables

Platform Discovery is your new dashboard for exploring everything Contentstack has to offer. Get a unified view of every capability available to your organization, and spot the ones you are missing out on.

With this release you can:

  • Audit your stack: See a complete inventory of your features in one glance.
  • Find hidden value: Instantly identify features marked No Recent Activity, powerful tools you already have access to but aren’t leveraging.
  • Scale intelligently: See clear pathways to advanced capabilities (like Personalization or AI) that align with your growth goals.

Platform Discovery_Changelog.png

Where to find it: Open the "App Switcher" in the top navigation bar and select Platform Discovery.

Read our documentation for more information.

We’ve introduced new taxonomy enhancements in Contentstack that improve how teams manage, publish, release, and govern taxonomy, making it easier to manage taxonomy structures across environments and locales.

Publish Taxonomies Independently

You can now publish taxonomies independently, similar to entries. This allows you to manage taxonomy structures separately from content publishing workflows.

With Taxonomy Publishing, you can:

  • Publish an entire taxonomy and its complete term hierarchy
  • Publish to specific environments and locales
  • Select a branch and apply locale fallback hierarchies
  • Schedule publishing jobs (if enabled)
  • Automate taxonomy publishing through APIs

Learn more about publishing a taxonomy.

Nested Reference Publishing Now Supports Taxonomies

Nested Reference Publishing now includes taxonomy support. When you publish an entry using Send with References, any referenced taxonomies:

  • Appear in the Publish References modal
  • Are included in the publish job
  • Publish their complete hierarchy to the selected environments and locales

This helps maintain consistency between published entries and their associated taxonomy structures across environments.

Learn more about working with Nested Reference Publishing.

Add Taxonomies to Releases

You can now add taxonomies directly to releases and deploy taxonomy structures alongside related content changes.

You can add taxonomies to a release from:

  • The Taxonomy Details page
  • The Taxonomy List page
  • Entry references, where associated taxonomy terms are automatically included when references are added

This helps teams schedule taxonomy deployments, streamline localization workflows, and reduce publishing inconsistencies.

Learn more about adding a taxonomy to a release.

Granular Taxonomy Permissions for Custom Roles (Early Access)

You can now assign taxonomy management permissions to custom roles without granting full administrative access to the stack.

Custom role users can manage taxonomy structures using permissions such as:

  • Create
  • Read
  • Update
  • Publish/Unpublish
  • Delete

You can also apply exceptions to restrict access to specific taxonomies or actions.

This enhancement separates taxonomy structure management from entry-level taxonomy permissions, giving teams more precise access control and governance flexibility.

To learn more, refer to the Permissions on Taxonomies documentation.

We’re excited to introduce Contentstack Assets, a modern, AI-powered digital asset management experience built for teams that need to organize, govern, and reuse assets at scale.

This upgrade moves beyond stack-based asset management to deliver a centralized, structured, and reusable asset system across your organization. With support for shared asset spaces, custom metadata modeling, localization, AI-powered enrichment, and advanced governance controls, Contentstack Assets helps teams streamline operations and deliver consistent digital experiences faster.

Key Features

  • Centralized Asset Management Across Stacks: Manage assets in dedicated spaces and reuse them seamlessly across multiple CMS stacks, reducing duplication and improving consistency.
  • Spaces and Workspaces for Better Organization: Organize assets by brand, team, campaign, or region using independent spaces and isolated workspaces for experimentation and campaign workflows.
  • Custom Asset Modeling: Create custom asset types and user-defined metadata fields to structure assets around your business needs, from campaign information to licensing and compliance data.
  • Native Asset Localization: Manage multilingual versions of assets within a unified workflow, including localized metadata and asset variants with fallback language support.
  • AI-Powered Asset Enrichment: Automatically generate alt text and tags for images to improve discoverability, accessibility, and SEO while reducing manual effort.
  • Visual Markups for Interactive Experiences: Add hotspots and bounding boxes to images to power shoppable content and richer visual experiences.
  • Advanced Search and Filtering: Find assets faster using metadata-driven filters, saved views, color-based filtering, and intelligent search capabilities.
  • Asset Versioning and Governance: Track changes to both metadata and binaries with built-in version history and rollback support.
  • Enterprise-Ready Access Control: Manage permissions using predefined and custom roles with support for SSO and SCIM-based user provisioning.

Contentstack Assets lays the foundation for a more intelligent, scalable, and future-ready asset strategy. We’re excited to see how your teams use it to create faster workflows, stronger governance, and richer digital experiences.

Check our documentation for full details, or contact support to get started immediately.

We are excited to introduce Clearwinner, a new Marketplace app designed to automate the post-test cleanup process for finished A/B test experiences.

Traditionally, concluding an A/B test requires manually identifying variant changes, merging them into baseline entries, publishing updates, and archiving the test. Clearwinner eliminates this time-consuming workflow with a single-click solution.

Key Features:

  • Automated Winner Identification: Easily view tests where Personalize has identified a winning variant based on statistical confidence levels (Has_Won, Leading_significantly, or Leading).
  • One-Click Merge & Publish: Automatically merge winning variant content into your baseline entries and publish the updates to your live environment in one background process.
  • Integrated Cleanup: Automatically archive concluded tests in Personalize and permanently delete redundant variant data to maintain a clean CMS stack.
  • Bulk Operations: Select and process multiple winning tests simultaneously to streamline large-scale experimentation cycles.

To learn more, refer to the Clearwinner App Installation Guide.

We’re improving the Mappings feature in Advanced Settings to make it clearer how values are resolved and how to work with nested configuration data. It now includes a dedicated Template Substitution section and better examples for nested values.

Dynamic values can already be used in request headers and body, and now they also work in URLs and query strings.

With a single syntax, {{ var.NAME }}, you can apply dynamic values across the entire outbound request. This enables API versioning, multi-tenant routing, pagination, and more, all driven from your configuration without hardcoding.

Learn more about Introduction to Advanced Settings in Developer Hub.

Here’s an overview of the latest updates in Contentstack Launch:

  • User-Agent Support in Cache Priming:

    Cache priming requests now include a dedicated User-Agent header, allowing you to easily identify and filter them from regular traffic in your logs.

    Learn more in Identifying Cache Priming Traffic.

  • Cancel Active Deployments:

    You can now cancel an ongoing deployment in Launch, allowing you to stop unintended updates before they are applied.

    Learn more in Cancel Deployment.

  • Support for Node.js 24.x:

    We've added support for the Node.js 24.x runtime, ensuring compatibility with the latest Node.js features and improvements.

    Refer to the Supported Node.js Versions.

  • Build Machines for Launch Builds:

    Launch now offers multiple build machine tiers, enabling you to allocate appropriate CPU, memory, and disk resources for faster and more reliable builds.

    To learn more, refer to Build Machines on Launch.

  • Server Machine Tiers for Launch Functions:

    With new server machine tiers in Launch, you can control CPU and memory allocation for your functions, ensuring better performance and scalability based on workload needs.

    For more details, refer to Server Machines on Launch.

  • Launch “Warming Up” Screen for Idle Environments:

    Launch now supports an automated warm-up state for inactive environments, where sites briefly scale down and quickly reinitialize on the next request to ensure efficient resource usage without impacting availability.

Managing entries just got faster. You can now switch between Publish Status, Release Status, and Publish Rules directly from the Entry Status panel using a dropdown. You can also apply filters to refine the displayed data. Selected filters remain applied across all views.

This update helps you focus on specific entry details without navigating multiple sections. For example, you can filter by environment and quickly switch views to check publishing status, release progress, or approval rules in the same context.

Refer to the view entry status documentation for more details.